I published an article on WordPress, but it doesn’t come up when I search for the hotel name or article title. Search Console shows “Not indexed”.At times like these, you may want to press “Request Indexing” over and over again.
However, there are different reasons why Google does not register a page, such as it has not been found yet after it was published, it has noindex attached, it considers another URL to be a legitimate page, or the content is almost duplicated. A request alone will not fix it.
In this article, the host, who is not familiar with IT, explains, explains how to read and search an important page in read-only mode together with AI tools such as Codex or Claude Code, and isolate the cause step by step.
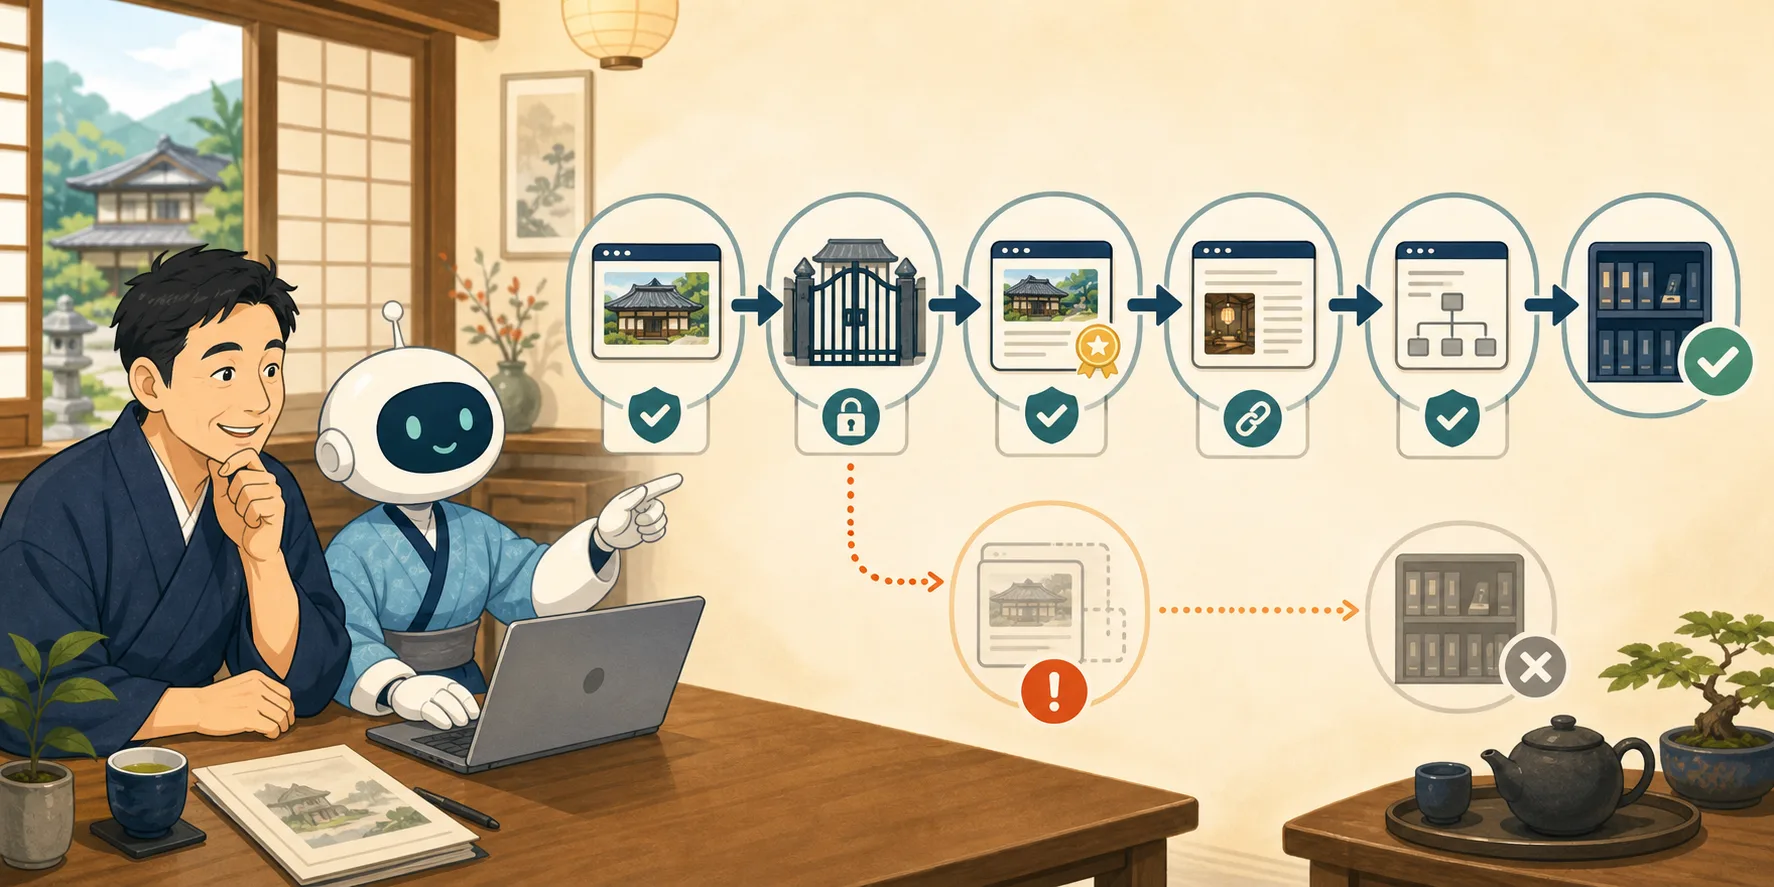
- Conclusion: Check in the order of publication, acquisition, registration permission, canonical URL, and discovery route.
- Difference between crawl and index
- Some pages are normal even if they are not registered.
- 1. Open the public URL in a person’s browser
- 2. See what Google knows with URL inspection
- 3. Check noindex
- 4. Don’t confuse robots.txt and noindex
- 5. Check canonical URL
- 6. Check if you can follow internal links
- 7. Check the site map
- 8. Check content duplication and amount of information
- How to read the main reasons for non-registration
- How to use indexing requests
- Read-only research text to ask AI
- Request to fix just one item
- Checklist after modification
- Summary
- Reference materials
Conclusion: Check in the order of publication, acquisition, registration permission, canonical URL, and discovery route.
Check in the following order.
- Decide if you really want to show the page in search
- Check if the public URL is HTTP 200 and anyone can open it.
- Check the current status with URL inspection in Search Console
- Check
noindexand HTTP headers - Check if robots.txt is preventing acquisition.
- Check if canonical points to the correct URL
- Check if it is included in the site link and site map
- Check for duplicate content or missing information
- Live test after fixing the issue and request once if necessary
Our goal is not to have all articles registered. There are some pages that should not be included in search, such as the reservation completion page, filter results, management page, and list of duplicate tags.
Difference between crawl and index
| Stage | Meaning |
|---|---|
| Discovery | Google knows the existence of the URL |
| Crawl | Google accesses the URL and retrieves the content |
| Index | Process the content and register it in the index for search |
| Search display | May be displayed in results depending on the search term |
Even if it’s indexed, it won’t show up in every search. Even the URL check “URL is registered with Google” does not guarantee that it will be ranked high for a specific search term.
Some pages are normal even if they are not registered.
Google’s page indexing report explanation explains that non-registration is not necessarily a problem.
If it is an accommodation site, the next page will confirm the purpose.
- WordPress admin screen and login
- Draft/Preview
- Reservation and inquiry completion page
- Site search results
- URL for narrowing down areas and conditions
- Duplicate URLs for printing, with parameters, etc.
- List of tags/dates with no content
- Verification environment/staging
On the other hand, if the main pages you want to provide to searchers, such as the top, guest room, rates, access, reservation information, resident cat introduction, and accommodation guide, are not registered, they will be subject to investigation.
1. Open the public URL in a person’s browser
First, open the public URL while logged out, not the admin screen.
- Displayed at HTTP 200
- Not 404 or 500
- Not asked for login or basic authentication
- No unintentional forwarding to another URL
- Text, images, and headings are displayed.
- Not “private” or “under maintenance”
- Main contents can be read on PC and smartphone
Even if the administrator is visible through cookies and login status, it may not be visible to Google or the general customer. Also check in a private window or another line.
2. See what Google knows with URL inspection
Google’s official URL inspection guide allows you to check what Google knows about a specific page, as well as live tests of published pages.
Enter the complete URL at the top of Search Console and note the following:
- Is it registered with Google?
- Was the page successfully retrieved?
- Is indexing allowed?
- Last crawl date and time
- Referrer page and site map
- user specified canonical
- canonical selected by Google
If “Verified URL” and “Google-selected canonical” are different, Google may be treating another URL as a representative.
Don’t confuse registered URLs with live tests
Regular URL inspection will show you the last state saved by Google. Live tests access the currently published page.
Live tests may be successful even if past errors remain immediately after correction. Conversely, even if the live test is successful, it may not be reflected in the index yet. Record both times and results separately.
3. Check noindex
noindex is an instruction that tells you not to add the page to the search index. In addition to the HTML robots meta tag, it may also be set in the X-Robots-Tag header of the HTTP response.
According to Google’s robots meta tag specification, if multiple instructions conflict, the more restrictive instruction will be applied.
WordPress checks the following:
- Search engine settings in “Settings → Display settings”
- SEO plugin post unit settings
- Classification settings such as categories and tags
- Output of themes and child themes
- Security/Maintenance Plugin
- HTTP headers for servers and CDNs
- Settings moved from staging to production
Before changing site-wide settings, check the affected area. Do not remove noindex for all categories or the entire site for a single article issue.
4. Don’t confuse robots.txt and noindex
robots.txt is a file that controls which URLs can be retrieved by search engine crawlers. noindex is an instruction to register the retrieved page in the index. Their roles are different.
Google explains that if you prevent retrieval in robots.txt, you will also not be able to read noindex on the page. Understand the relationship between “I don’t want it to appear in search, so stop with robots.txt” and “Get the noindex to read it” and set it up.
If an important page is prohibited in robots.txt, find out why there is that rule. If you delete lines that don’t make sense, it may open up administrative URLs or a large number of unnecessary URLs, so we don’t let the AI delete them automatically.
5. Check canonical URL
Canonical is information that indicates which URL you want to treat as the representative when multiple URLs have the same or similar content.
Check for the following deviations.
- Published articles make the top page canonical
- Points to another URL, such as without
httporwww - refers to staging or old domain
- Incorrectly specified URL of another article
- Sitemap and canonical are different
- Internal link points to duplicate URL
- Transfer destination and canonical are inconsistent
Google’s canonical official guide recommends that redirects, rel="canonical", sitemaps, etc. are clues to the canonical URL, and that internal links are also standardized to the canonical URL.
Even if Google chooses another URL as canonical, there is no need to modify it if it is a valid duplicate integration. If pages with different content have been merged by mistake, check not only the title but also the uniqueness of the body, internal links, and canonical settings.
6. Check if you can follow internal links
Isolated pages are difficult to find outside of the sitemap, and customers cannot find them. Link to important pages from places that suit the context, such as the top page, categories, area list, related articles, information pages, etc.
Google advises in its Official Guide to Links that important pages should be linked from at least one page within your site, and that the link wording should make the content easier to understand.
- Can it be followed as a normal link without relying only on JavaScript?
- Is the destination URL forwarded or has a typo?
- Is the wording easy to understand, not just “here”?
- Do you want to proceed from the category or information page instead of making the menu too long?
- Did you link to it from a related existing article after publication?
It is created not only for search engines, but also as a guide for people considering lodging to find the information they need.
7. Check the site map
A sitemap is a means of informing Google of the existence of a URL, and does not guarantee registration.
The items to check are as follows.
- Sitemap URL opens with HTTP 200
- Search Console can be obtained
- Contains the target canonical URL
- Do not include
noindexpages or forwarding URLs unnecessarily http,https,wwwhave been unified.- Deleted URLs do not remain
- Multiple SEO plugins are not creating separate sitemaps
Google’s Sitemap Creation Guide guides you to include the full URL of the canonical URL you want to display in search results.
8. Check content duplication and amount of information
Even if the technical settings are correct, if the content is almost the same as another page, Google may treat only one page as representative.
Examples that tend to occur on accommodation sites are as follows.
- A short list article with only the region name changed
- The same inn was given almost the same description in multiple URLs.
- List of posts with the same category, tag, and search results
- Print URL and regular URL have the same text
- Separate URLs for PC and smartphone
- Mass-produced branch articles with different titles but the same conclusion
Rather than increasing the number of characters by adding generalizations to thin pages, we will consider ways to integrate them into existing pages, add unique comparison information, and organize unnecessary duplicate URLs into regular URLs.
How to read the main reasons for non-registration
| Display example | General meaning | First check |
|---|---|---|
| Detected/unregistered | URL known but not obtained or registered | Internal links, site map, server status |
| Crawled/unregistered | Obtained but not currently registered | Content, duplicate, canonical, quality |
| Excluded by noindex | There is an instruction not to register | Is this the intended setting |
| Blocked by robots.txt | Acquisition prohibited | Purpose and scope of the regulation |
| Duplicate/different canonical URL | Treating other URLs as representative | Validity of Google selection canonical |
| Redirect | Transferred to another URL | Is the final URL a legitimate page |
| 404/Soft 404 | Determined that the page does not exist or has no content | HTTP status, text, deletion intent |
| Server error | 5xx etc. occur when retrieving | Appearance monitoring, server log, recurrence status |
The display name may change depending on screen updates and circumstances. Instead of modifying just the reason name all at once, inspect the target URL one by one.
How to use indexing requests
After fixing the issue, you can check acquisition and registration permissions with a live URL test, and request registration if a single page is important.
Google officially advises that you use URL inspection for single pages and sitemaps for multiple pages. There is a limit on requests, and sending them does not guarantee registration or ranking.
Avoid the following usages.
- Hit the same URL every day
- Send noindex or 404 without fixing it
- Send bulk URLs one by one
- Try to register all duplicate articles
- Change the title and URL many times until it is registered
- Treat as a button to increase ranking
Read-only research text to ask AI
The following WordPress public pages are not registered in Search Console.
Please do not change any settings or articles yet and investigate in read-only mode.
[Full public URL]
[Search Console reason and last crawl date and time]

Make sure:
- HTTP status and final URL
- Publication status and text display
- robots meta and X-Robots-Tag
- Applicable rules for robots.txt
- canonical URL
- Whether site map is posted or not
- Internal link to that page
- Forwarding, duplicates, similar articles

Please separate confirmed facts, candidate causes, unconfirmed matters, and suggested corrections.
Please do not change WordPress, SEO plugins, robots.txt, or servers yet.
Do not perform indexing requests either.
Request to fix just one item
Please make only one correction proposal based on the results of your investigation of unregistered pages.
[Survey results]

Target URL, current value, proposed value, scope of influence, basis, how to restore,
Please show the corrected live test items.
Unindex the entire site, delete robots.txt all at once,
Please do not replace canonical all at once or mass-produce similar articles.
Do not make any production changes yet.
Checklist after modification
- [ ] Confirmed whether it is an important page that you want to include in search
- [ ] Public URL opens with HTTP 200
- [ ] There is no certification or maintenance display
- [ ] You can get the page with live test
- [ ] Indexing is allowed
- [ ] No unintended noindex or X-Robots-Tag
- [ ] Not confusing the roles of robots.txt and noindex
- [ ] canonical points to the correct representative URL
- [ ] Follow from internal link
- [ ] Sitemap includes canonical URL
- [ ] Confirmed the relationship with duplicate/similar pages
- [ ] Recorded modification date and rationale.
- [ ] Requested registration of only one necessary page
- [ ] I made a plan to recheck the status in a few days.
Summary
Not being indexed is not a problem with the number of requests. First, determine whether the page needs to be included in search, and isolate the cause in the order of publication status, acquisition, registration permission, canonical, internal links, sitemap, and content.
AI can help read and examine HTML, HTTP headers, links, and sitemaps, and organize the verification results. However, please do not automatically change robots.txt, noindex, and canonical for the entire site at once. It’s safe to fix one page, live test it, record it, and then move on.
To install Search Console and confirm ownership, please refer to Introduction to Google Search Console for the host, and for technical confirmation immediately after publication, please refer to How to confirm after WordPress publication. For improvements after the non-registration is fixed, proceed to How to grow existing articles from search terms in Search Console.